Articles
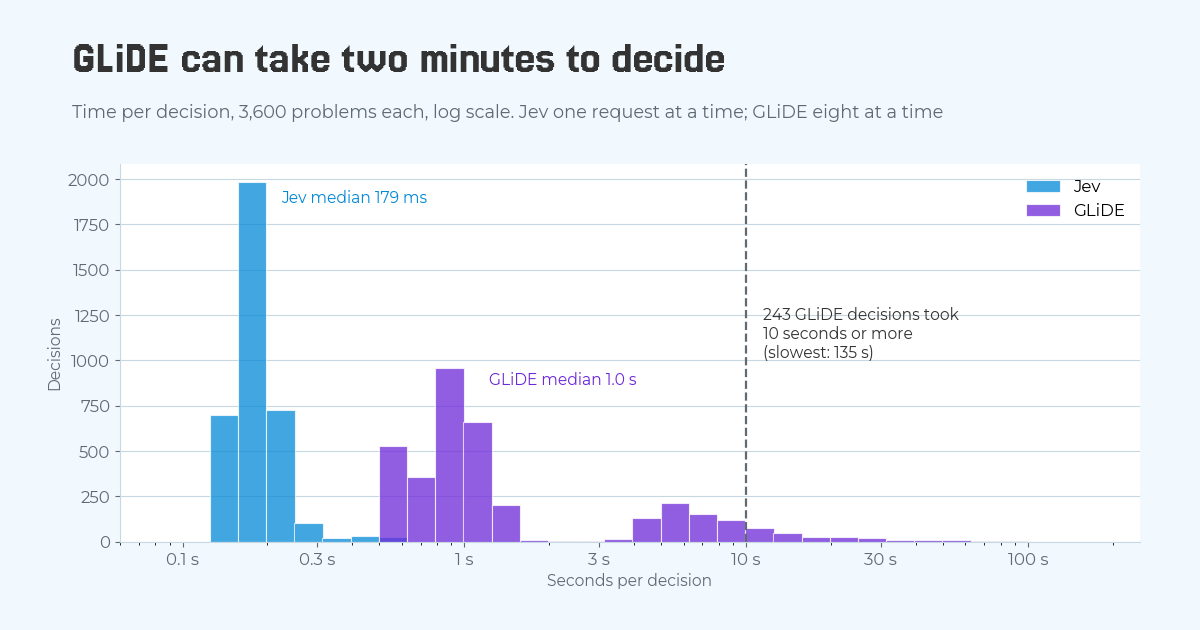
It's Not a System 1 Model If It Takes Ten Seconds
October 2, 2026Fastino's GLiDE beats every open model on our reasoning benchmark, but not Jev: less accurate, five times slower, ten times the cost, and a confidence that barely tells right from wrong.
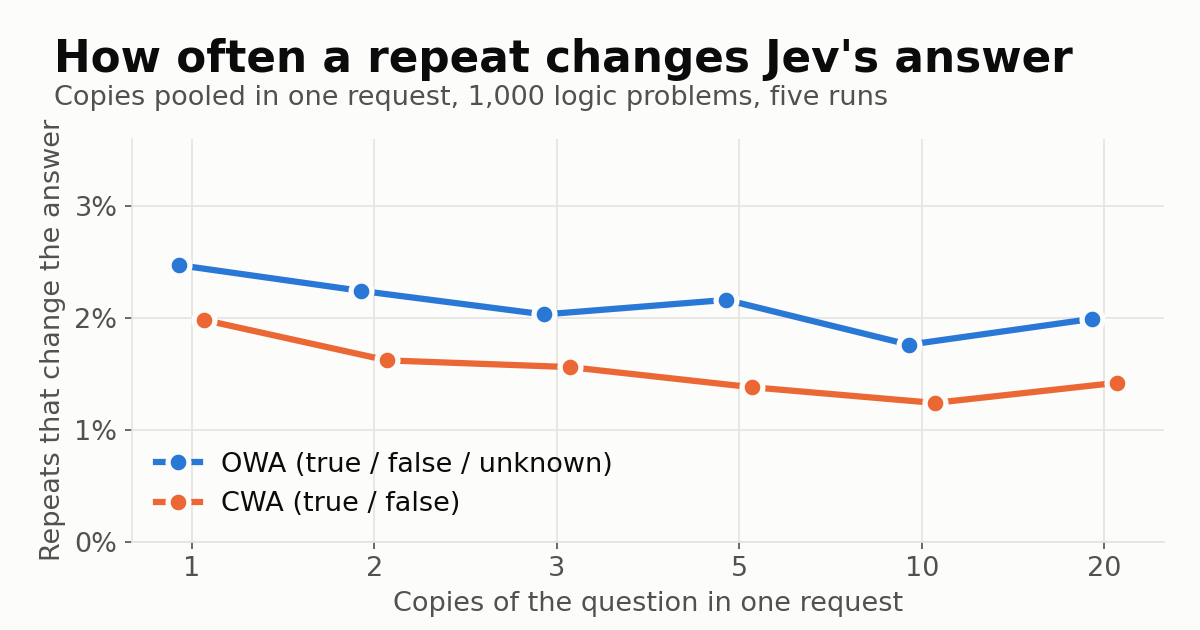
Can Averaging Reduce Noise in an AI Decision Model?
October 1, 2026We asked Jev the same question ten times in one request and expected ten identical answers. They split, four votes to six. Kahneman, Sibony and Sunstein call that kind of variation noise. Averaging the copies didn't make Jev more accurate, but it cut changed answers on a rerun by about a third.
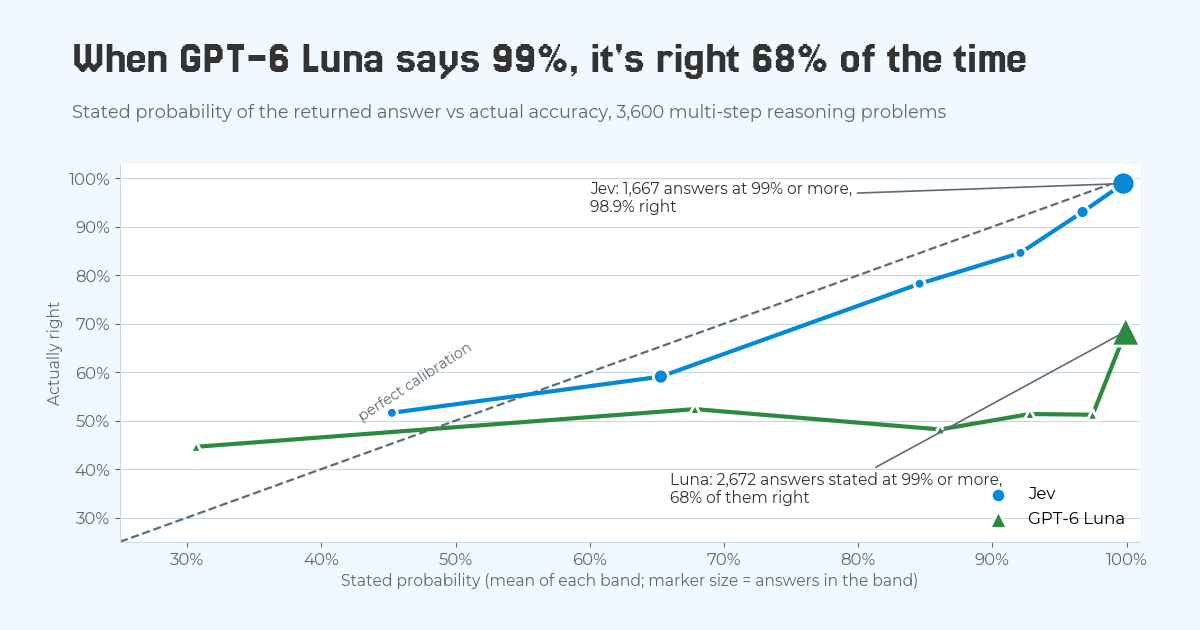
The OpenAI Decisions API Needs a Confidence You Can Trust
October 1, 2026We've routed decisions on LLM confidence since 2023, and calibration is what we most hope OpenAI's new Decisions API gets right. The model underneath, GPT-6 Luna, isn't there yet: on 3,600 reasoning problems its 99% meant 68%, and by five inference steps it was at a coin flip.
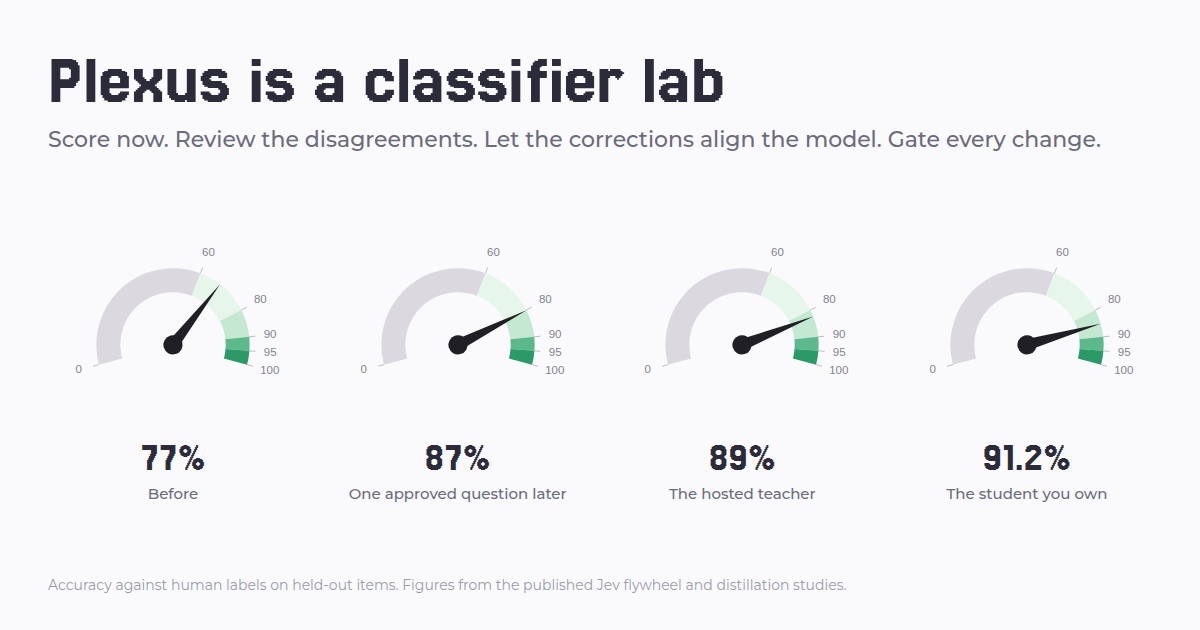
Plexus Is a Classifier Lab: Operationalizing Classifiers at Scale
September 27, 2026A hosted decision model sat at 77 percent accuracy through 87 rounds of reviewer feedback, then one approved question took it to 87. Here is the loop that did it, every figure published, and the offer to run it on your judgment task.

Earlier
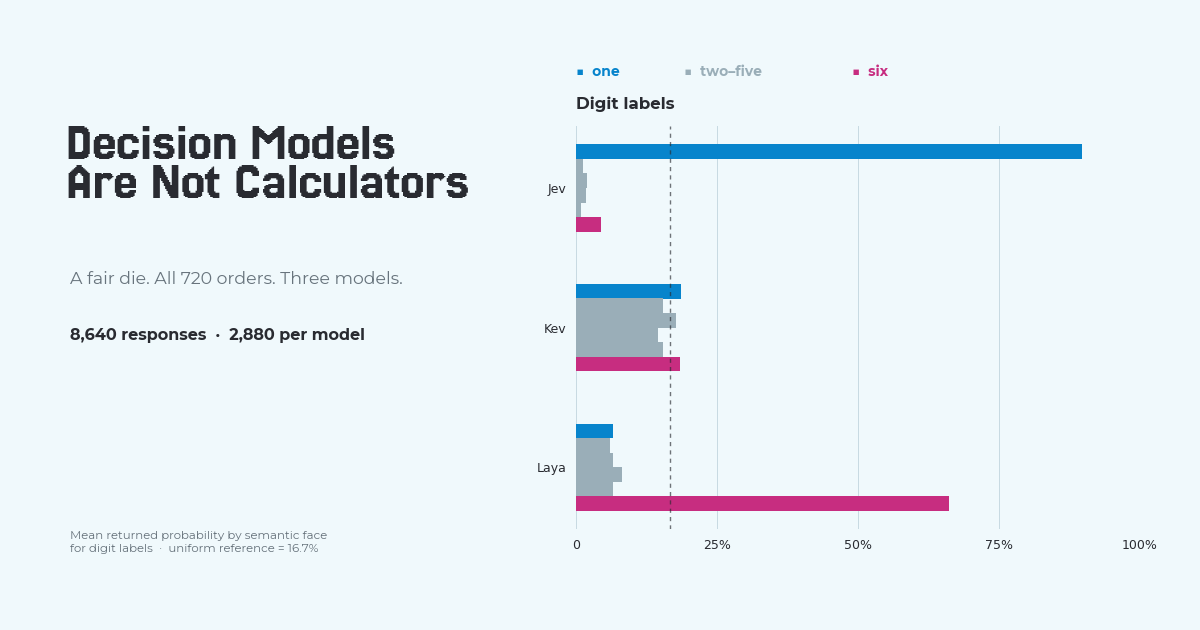
Decision Models Are Not Calculators
Jev chose one in every ordering of a fair-die question; Kev leaned toward one, and Laya overwhelmingly chose six. Benford's Law remains a hypothesis.
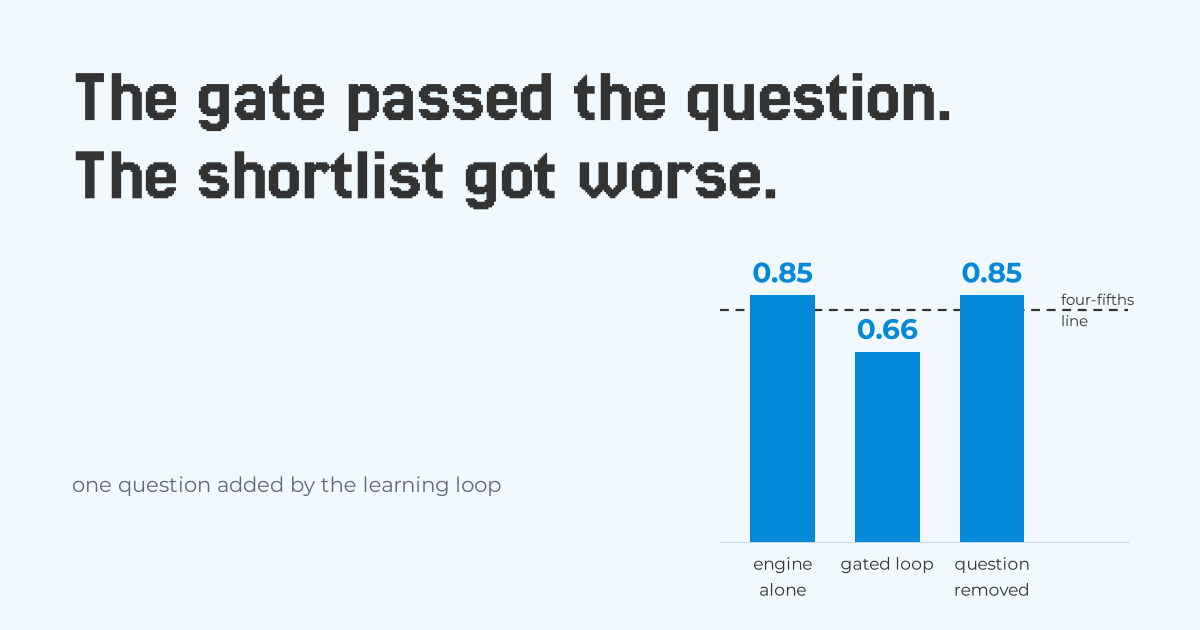
Can You Fix It? Gating, Averaging and Fine-Tuning Against a Gendered Verdict
A decision model's verdict moves on "she". We put a gate on the learning loop that rejects any question whose answer moves with the pronoun. It kept out the obvious ones and still made a hiring shortlist worse, because a question can ignore the pronoun and read gender from the words. Here's what worked instead.
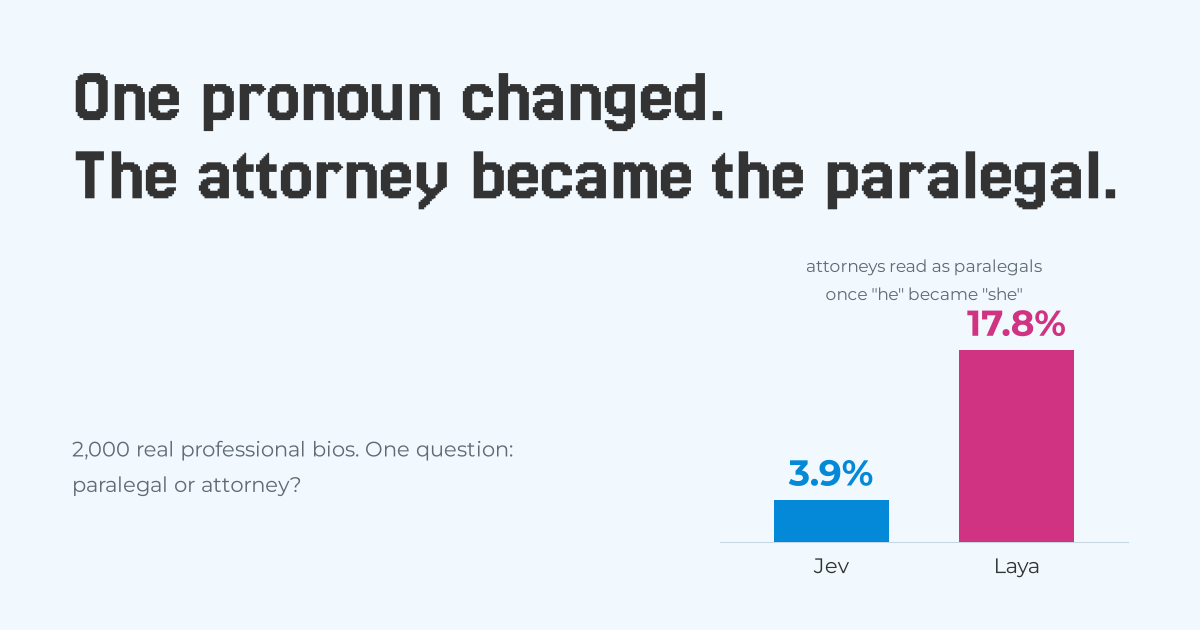
We Told the AI She Was a Woman. It Demoted Her
A new kind of AI, the decision model, makes instant decisions about people: who gets an interview, whose claim gets flagged. It's cheap and fast, and companies are adopting it without checking what it does. We checked. It quietly ranks women lawyers below men, and every company using it makes the same mistake.
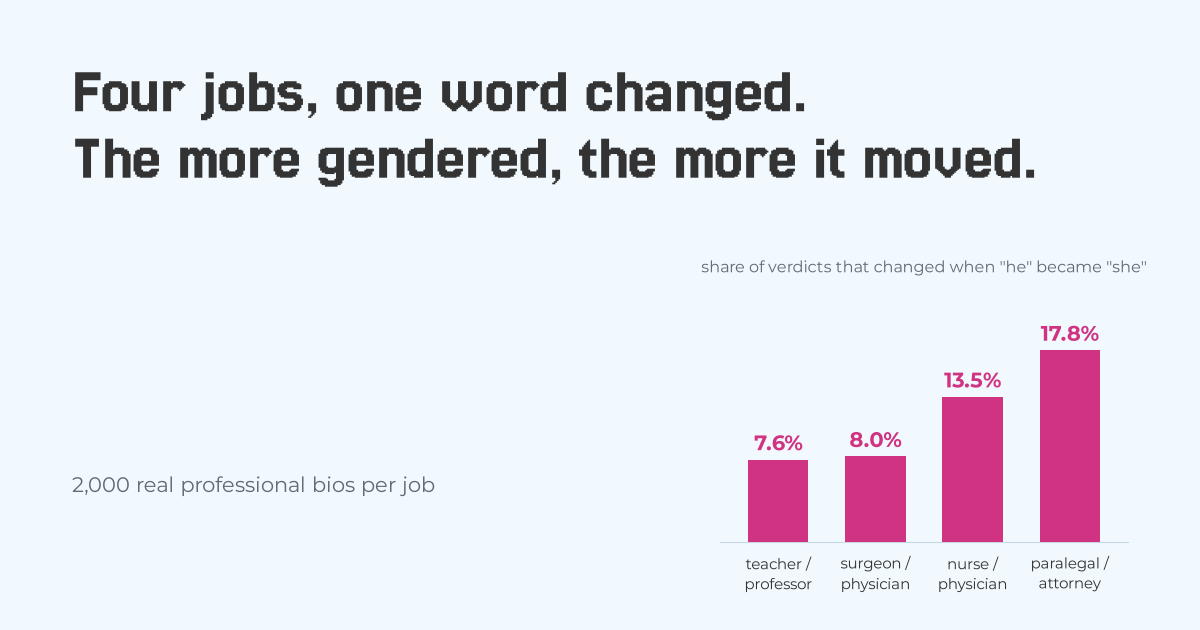
The One-Word Test: How Jev and Laya Read Gender, Race and Age
Two thousand real bios per job, first names blanked, one pronoun swapped, both decision models asked twice. Laya's verdict moved on 8 to 18 bios in 100, Jev's on 1 to 4, almost always toward the stereotype. Here is the method, the jobs, the shortlist, and what names and ages do.
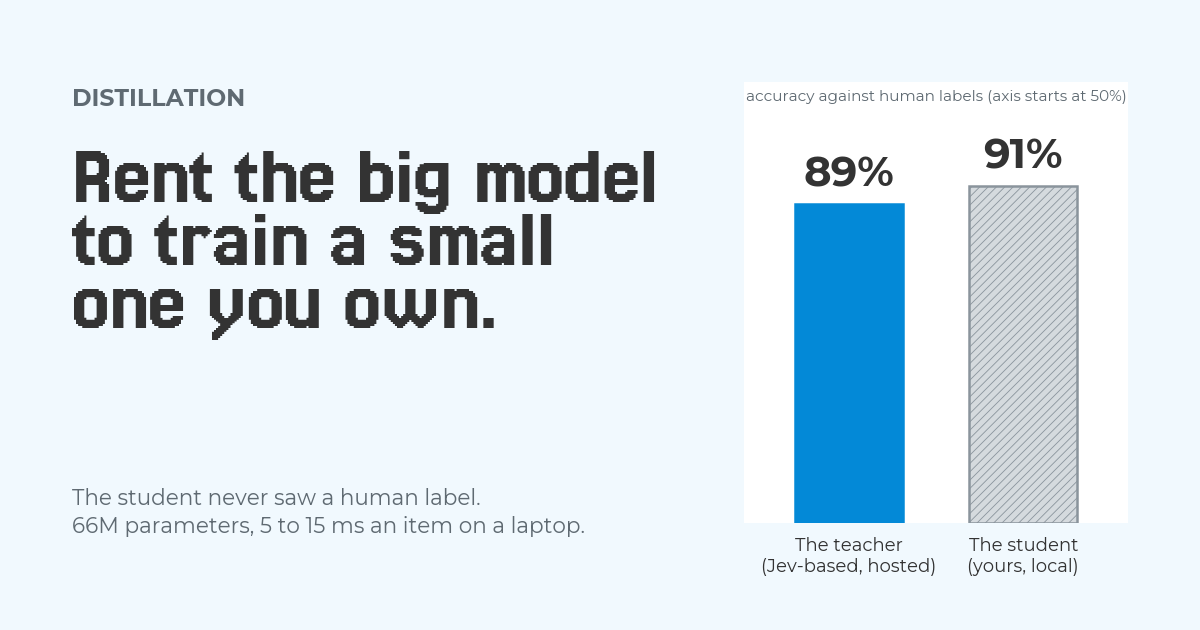
Distilling an Aligned Jev System into a Classifier You Own
A Jev decision model aligned with 140 human labels taught a 66M-parameter DistilBERT that scored 0.912 against the human label, two points above its teacher, at 5.6 to 15 ms an item. The accuracy is the least general part; the per-slice ship gate is the part to copy.
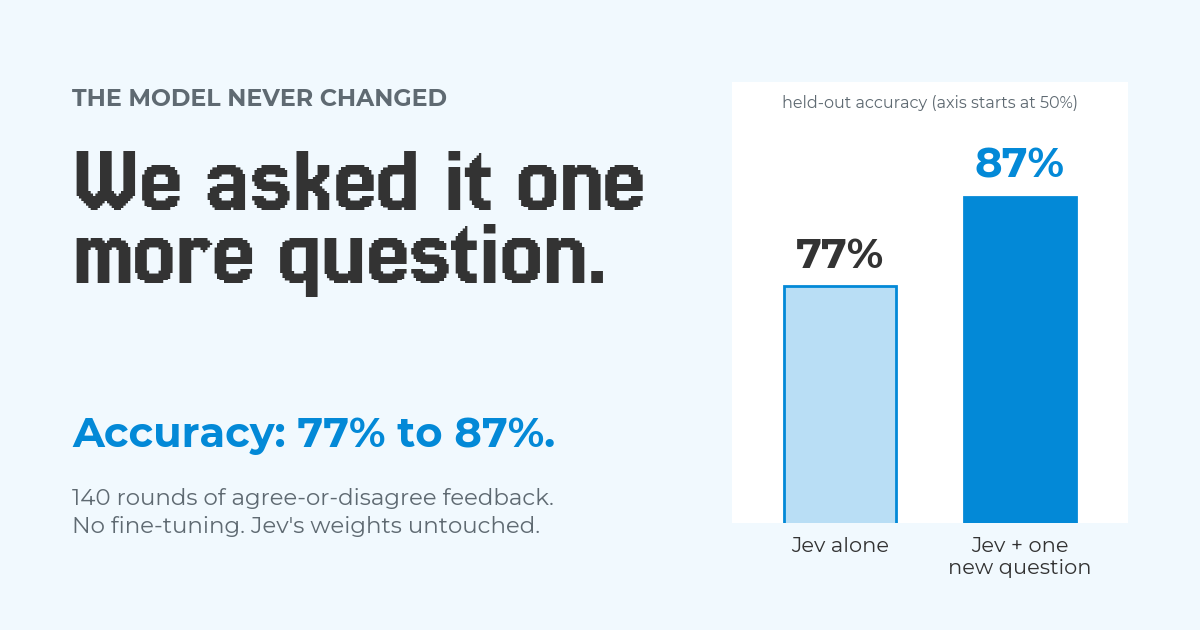
Fine-Tuning Jev: You Can't. Here's What Gets You the Same Effect
You can't fine-tune Jev, or any hosted decision model: TypeSafe serves the same weights to everyone. So we kept it frozen and adapted the questions and a small fitted head around it. On 140 labels, one new plain-English question bought 10 points of accuracy, and it finds the hidden pattern about a quarter of the time.
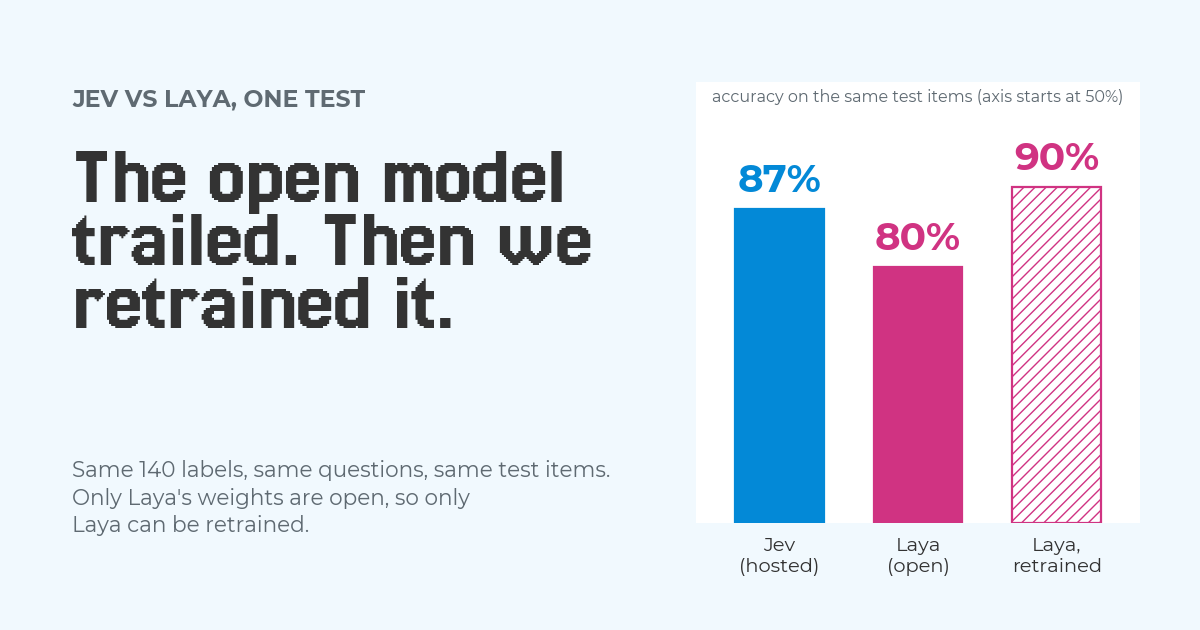
Jev vs Laya: Same Labels, Same Questions, One Variable
We ran two decision models, Jev and the open-weights Laya, through one harness where only the engine changes. Jev led by 4.7 points alone and 6.8 with our feedback layer, and then fine-tuning Laya on the same 140 labels beat both.
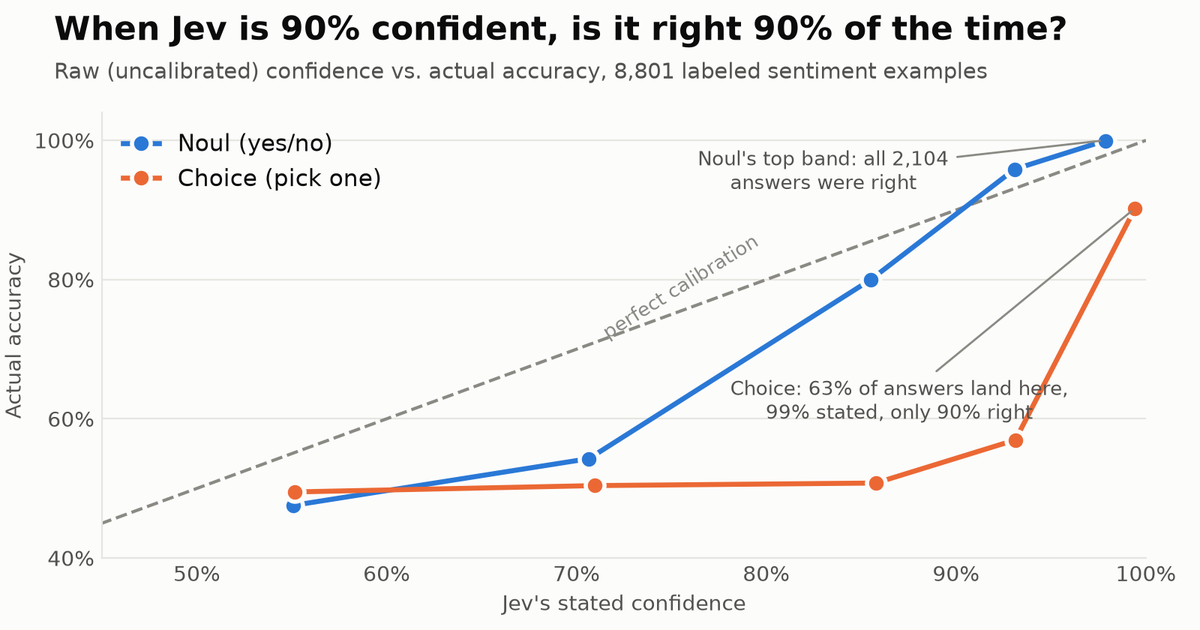
Can You Trust Jev's Confidence?
A decision model's confidence should mean something. Jev's does: higher really does mean more likely right. But on 8,801 labeled examples they ran overconfident, and how you phrase the request changes the pattern. Calibration fixes most of it.