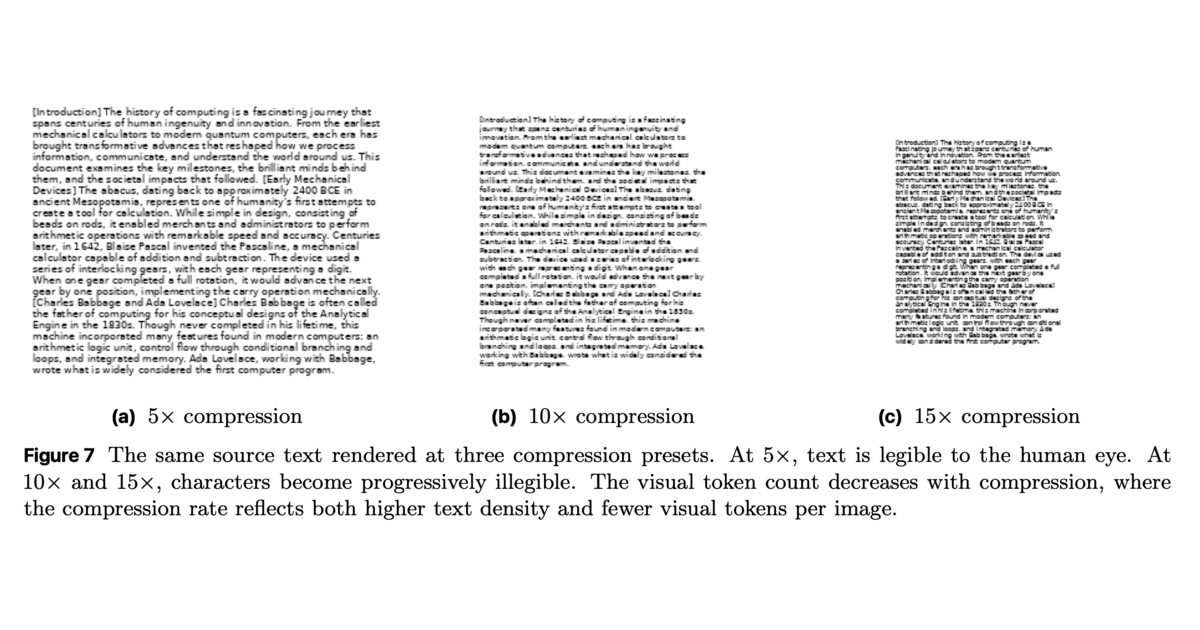
Text as an Image, Then a Magnifying Glass
Text as an Image, Then a Magnifying Glass: LensVLM compresses text by showing it to a vision-language model as an image, then opens the original text where the answer lives.
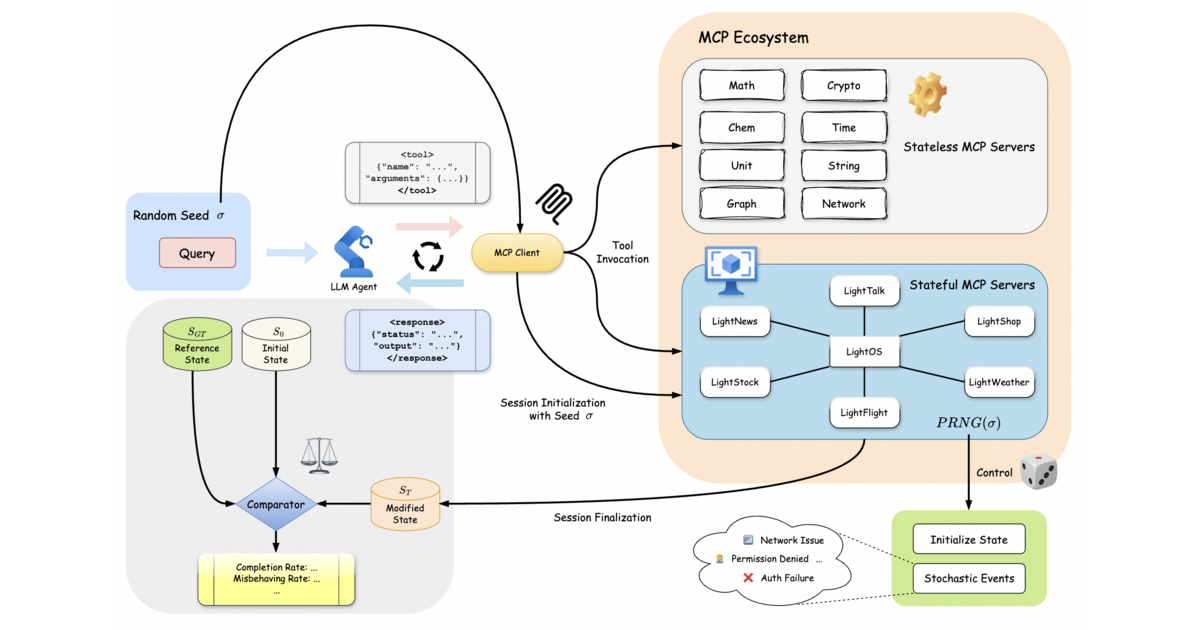
Fine at 15 tools, lost at 300
ComplexMCP puts agents in stateful MCP sandboxes with hundreds of interdependent tools. Retrieval saturates, checks get skipped, and recoverable errors become surrender.
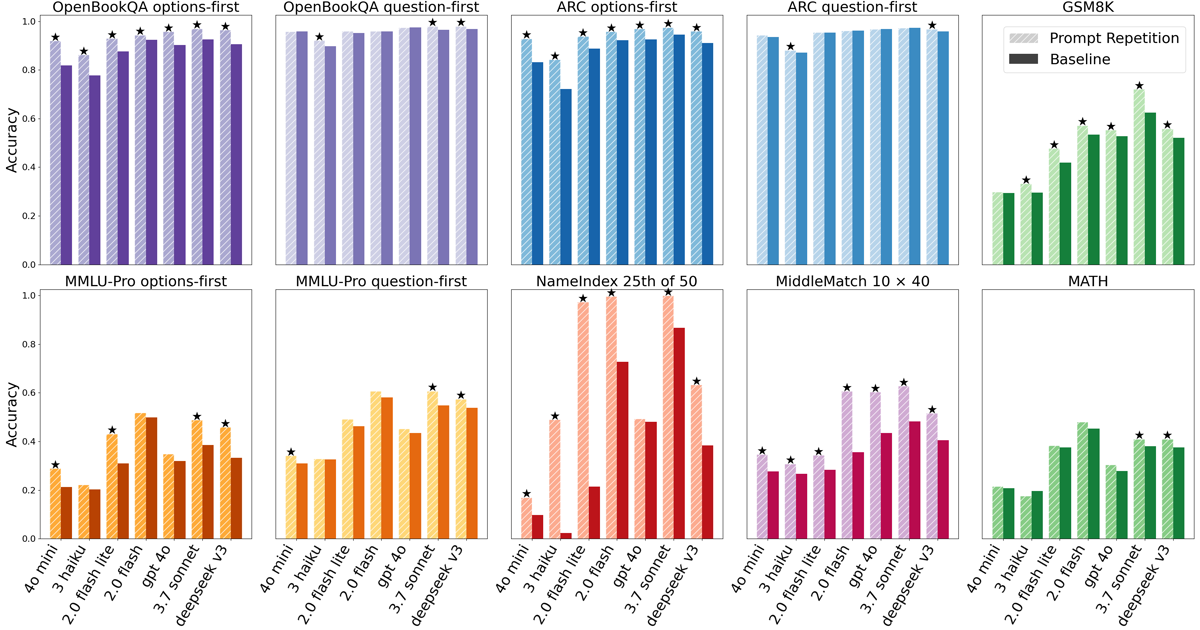
Repeat the prompt when the model is not reasoning
When reasoning is off, send the query twice. Gemini, GPT, Claude, and Deepseek all improved, with no extra output tokens and no extra latency.
A vending machine is a long-horizon eval
Vending-Bench asks an agent to run a snack machine for a long time. The hard part is not stocking. It is staying coherent after the twentieth day.
The recipe is the news, not the model
DeepSeek-R1 is not a secret model. It is an open recipe: RL on verifiable rewards, then distill. Frontier reasoning behavior just got cheap to copy.
Change the numbers and the math falls over
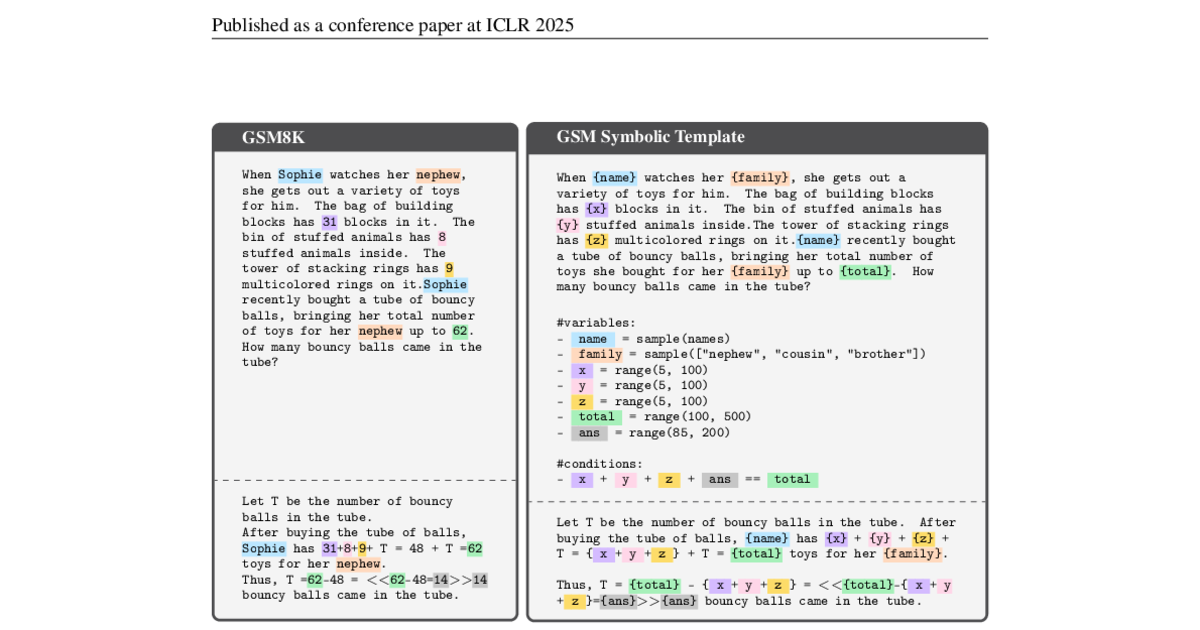
Apple's GSM-Symbolic paper shows that grade-school math scores are fragile. Swap the numbers, or add an irrelevant clause, and apparent reasoning collapses.
Automated Scientific Discovery
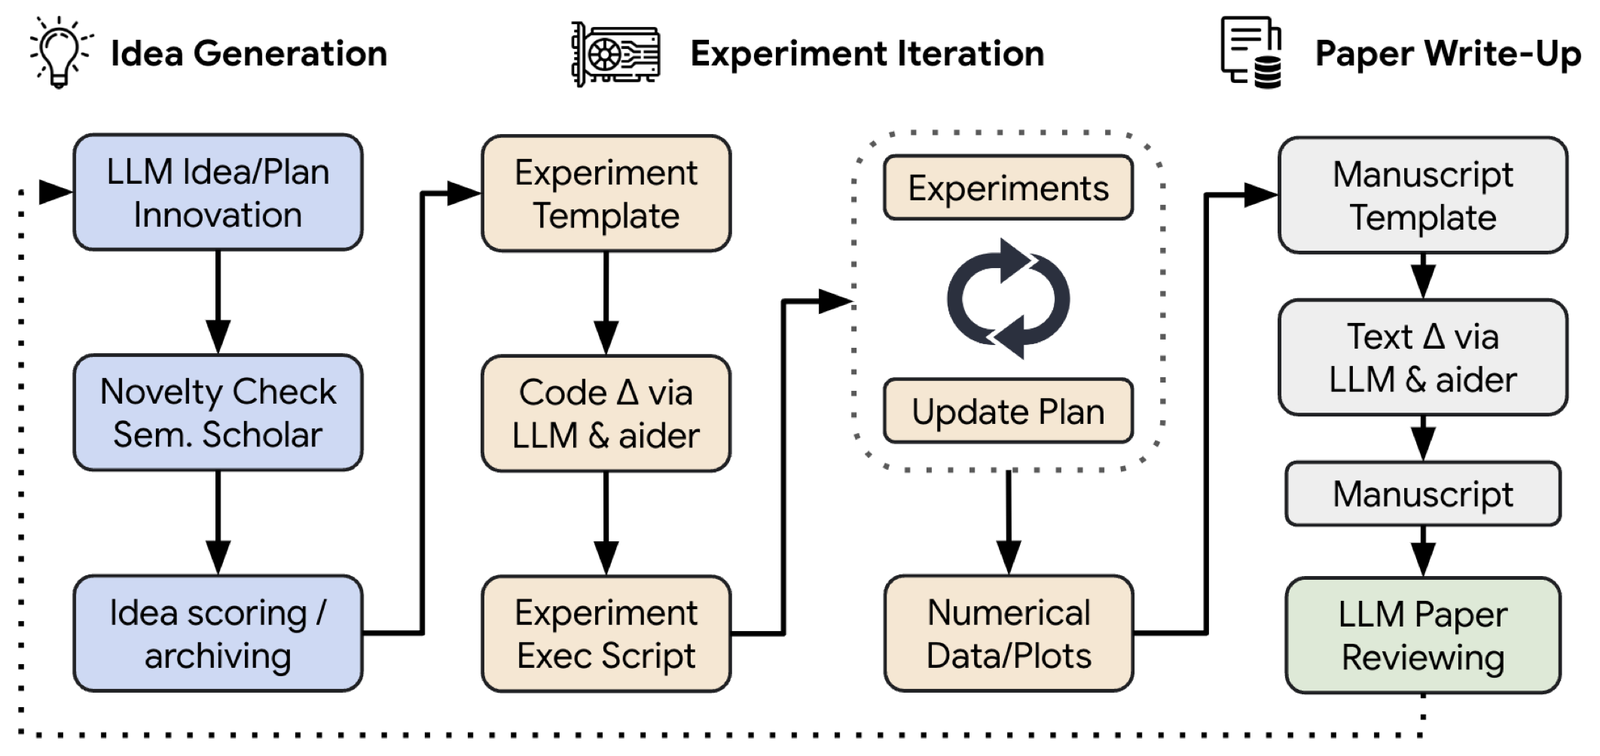
Two recent papers touch on the trend of automated scientific discovery, exploring AI-driven research assistance and fully autonomous scientific experimentation.
Mixture of Agents
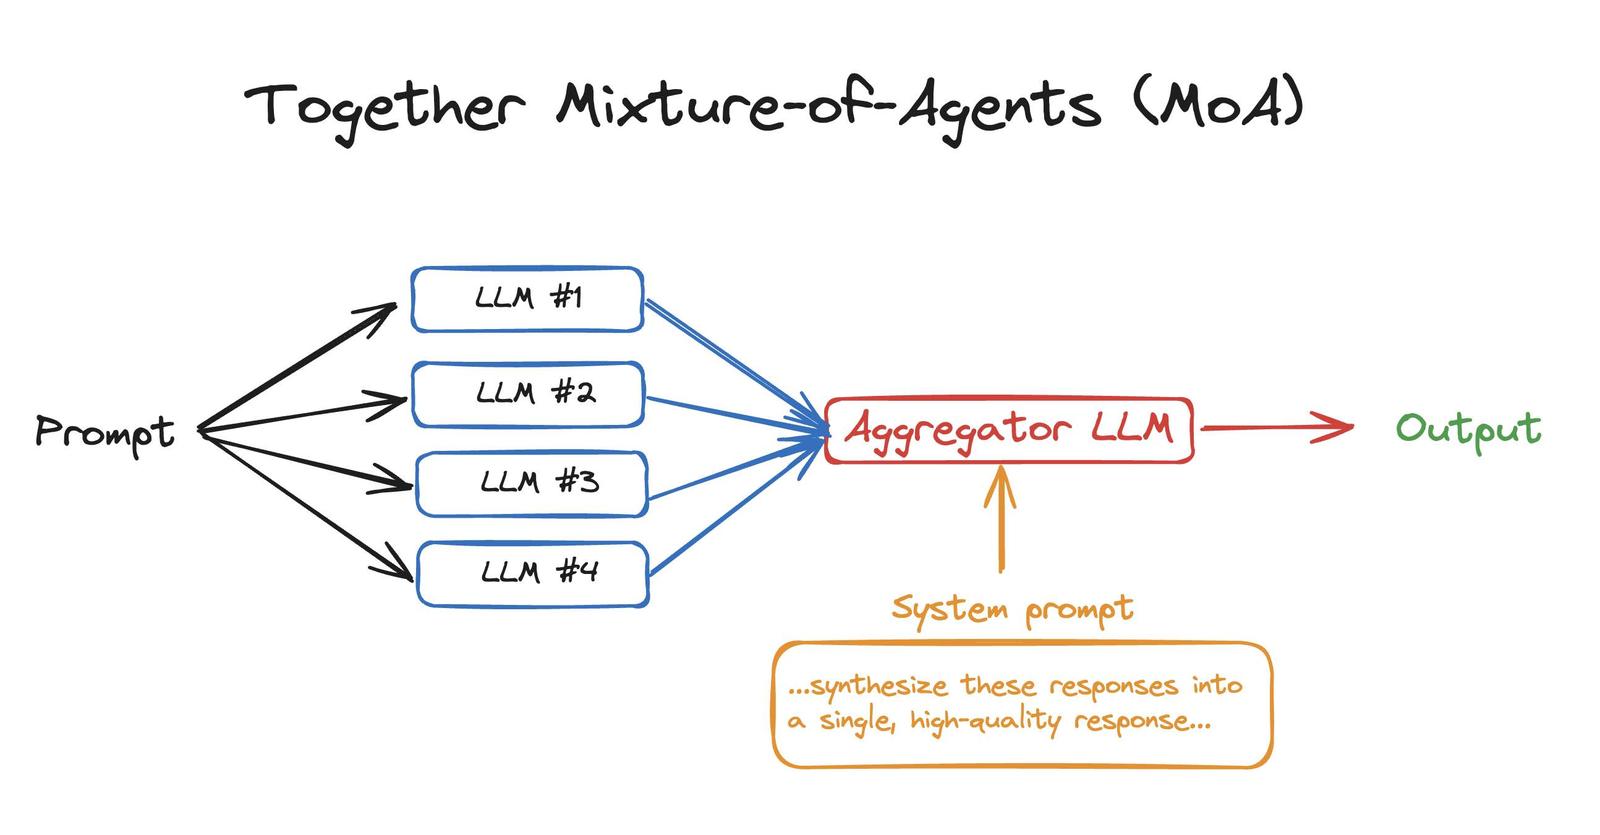
Together AI is the latest to demonstrate that agentic orchestration of cheap LLMs can produce better results than directly using expensive LLMs.
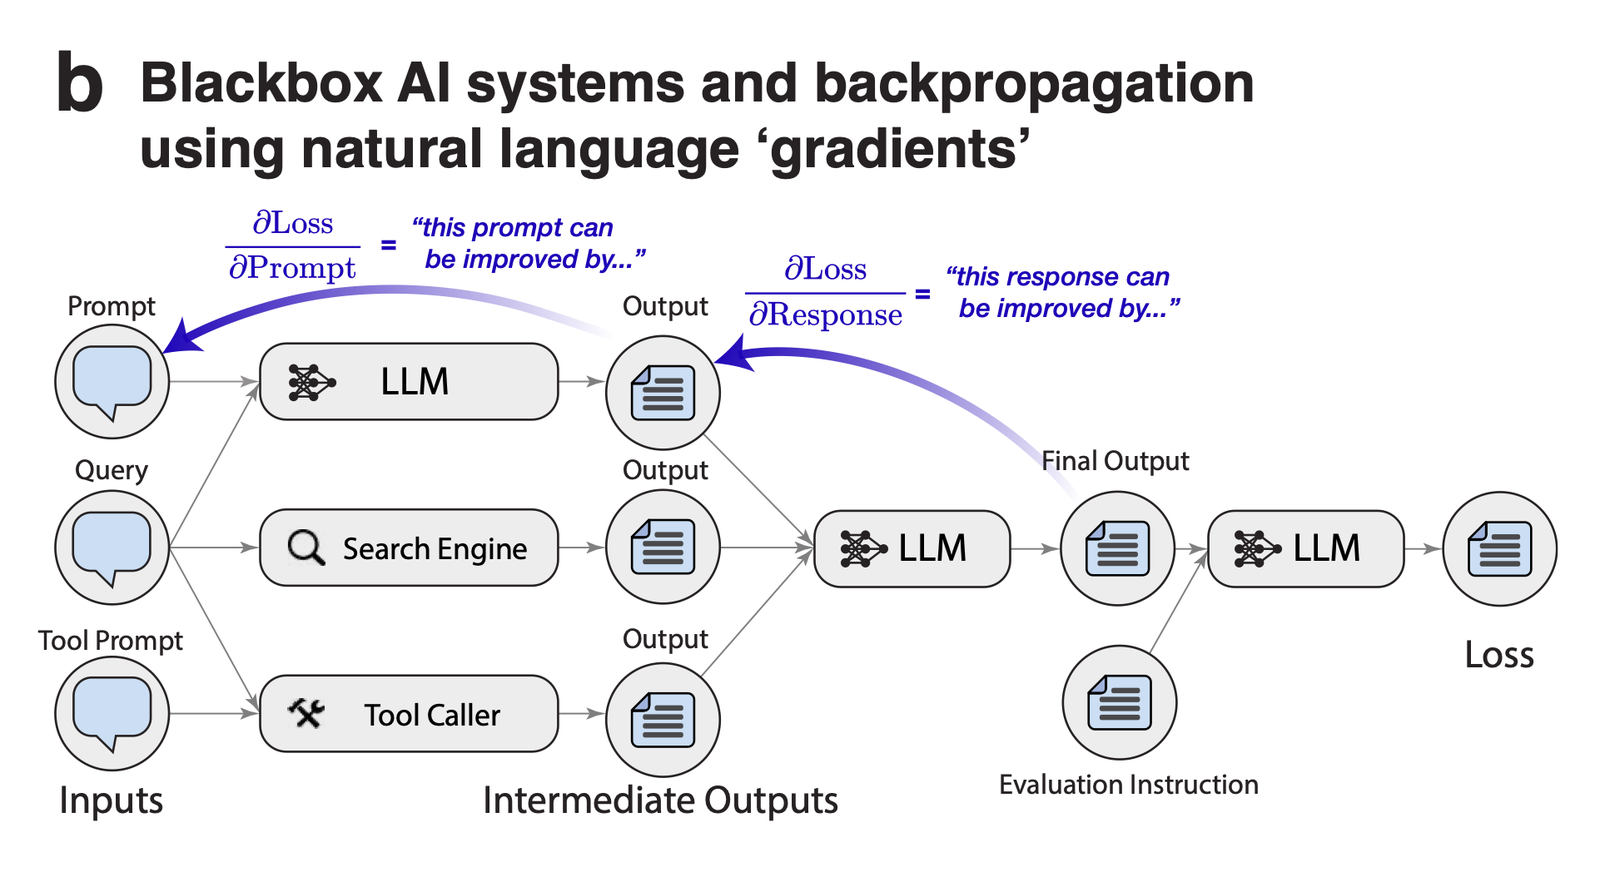
TextGrad
In the paper "TextGrad: Automatic 'Differentiation' via Text", researchers from Stanford introduce a framework for automatic differentiation via text, for LLMs.